Social & Videos
Short social takes on our content and our shorts, long-form and product videos, all in one stream with the newest first. Swipe through one at a time and follow through to the full article when you want more.
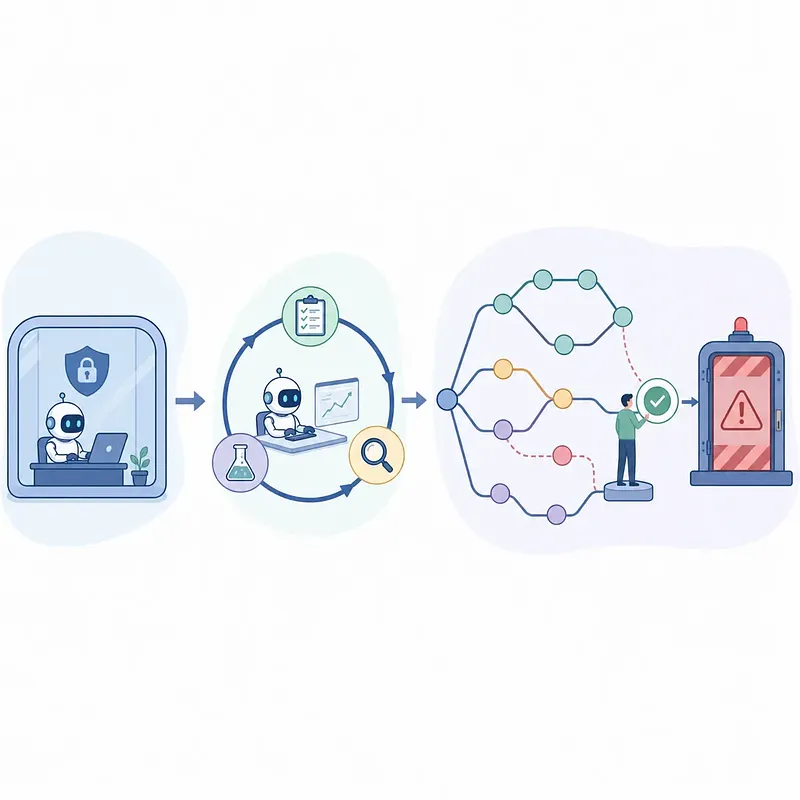
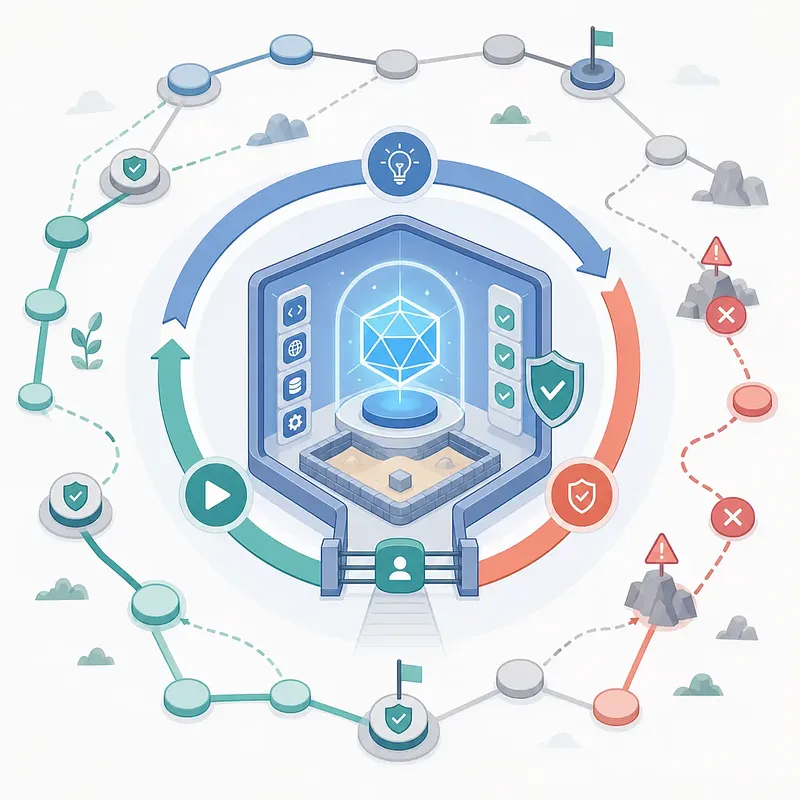
AI agent architecture is often discussed through three practical perspectives rather than one officially standardized classification. Harness engineering covers the execution environment around the model: context, tools, permissions, validation, logging, and approval procedures. Loop engineering defines how planning, execution, validation, and revision repeat—and when they must stop. Graph engineering makes permitted states and transition paths explicit. Why does this matter? Many organizations may gain more from improving a single agent’s harness and evaluation framework than from immediately constructing a complex multi-agent graph. For high-risk code, governance must also extend beyond approving an AI-generated summary to verifying tests, change scope, security boundaries, and original artifacts. #AIAgents #HarnessEngineering #AIDevelopment
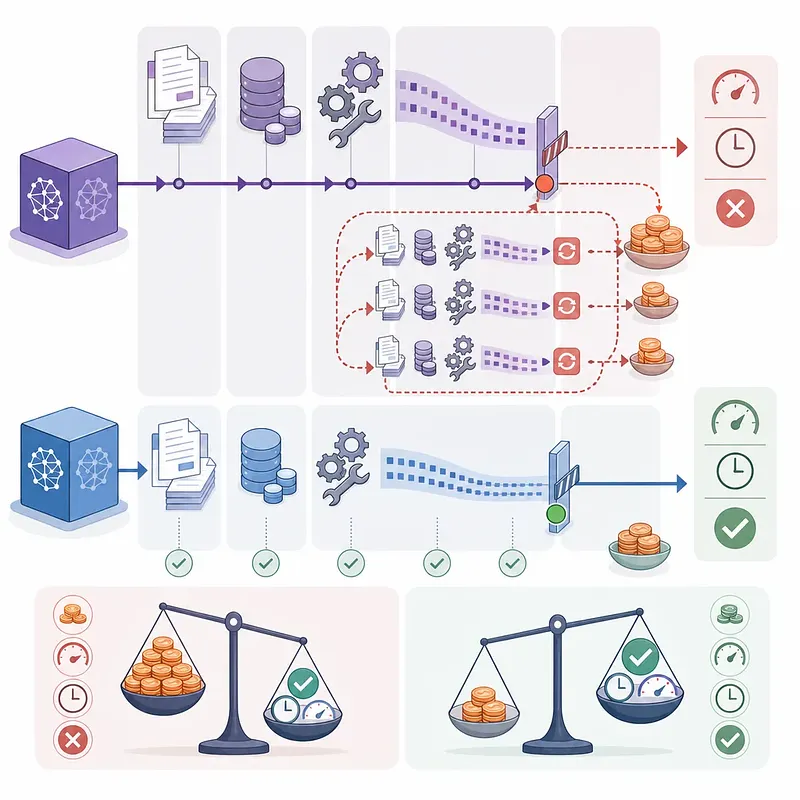
AI teams price a 500K Grok 4.6 run. Its list price is under half the price of two peers, but inputs over 200K may cost twice the rate. That makes workload architecture—not sticker price—the key cost variable. At launch, the model scored 61 on the Artificial Analysis Intelligence Index, placing it close to top-tier models. However, a small difference on one aggregate benchmark cannot establish accuracy, reliability, task-specific quality, or tool-use performance. Retry rates also change effective cost. The article explains how the input-output token mix and long-input surcharge shape spending relative to GPT-5.6 Sol and Claude Opus 5. It also shows why retrieval and context compression should be designed together for large code repositories, long document collections, and extended agent tasks. Engineering leaders, AI platform teams, and procurement professionals evaluating these workloads should read the analysis before selecting a model on benchmark score or list price alone. #GenerativeAI #AIAgents
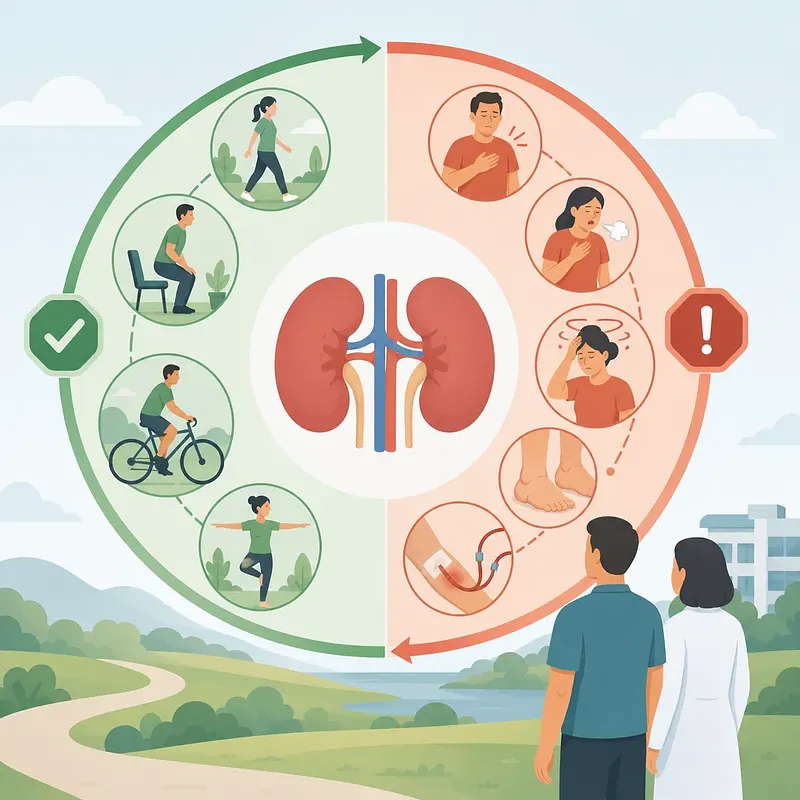
콩팥병이면 무조건 쉬어야 한다? 운동과 절대안정의 기준
인조이스 injoys.com 안정적인 만성콩팥병 환자에게 장기간의 절대안정이 필요한지 알아봅니다. 운동의 현실적인 이점과 운동보다 의료진 평가가 우선인 상황을 함께 정리했습니다. 전체 콘텐츠는 채널 프로필의 링크에서 보실 수 있습니다. 주소로 바로 여시려면 아래를 복사해 주세요. https://injoys.com/ko/articles/chronic-kidney-disease-exercise-and-bed-rest 매일 새 소식을 받아보시려면 구독해 주세요. #만성콩팥병 #콩팥건강 #운동기준 #건강정보

Claude Code 기초 가이드 설치부터 권한 모델 컨텍스트 관리까지
Claude Code를 처음 사용하는 사람을 위한 단계별 기초 가이드입니다. 설치 전 준비, 프로젝트 폴더에서의 첫 실행, 안전한 요청 방법을 살펴봅니다. Plan, Default, Accept Edits 등 권한 모드의 차이와 모델 선택, 비용 관리, 컨텍스트 정리 방법도 설명합니다. CLAUDE.md 작성법과 Git, 테스트, 사람의 검토를 결합한 실전 작업 절차까지 한 번에 정리했습니다.
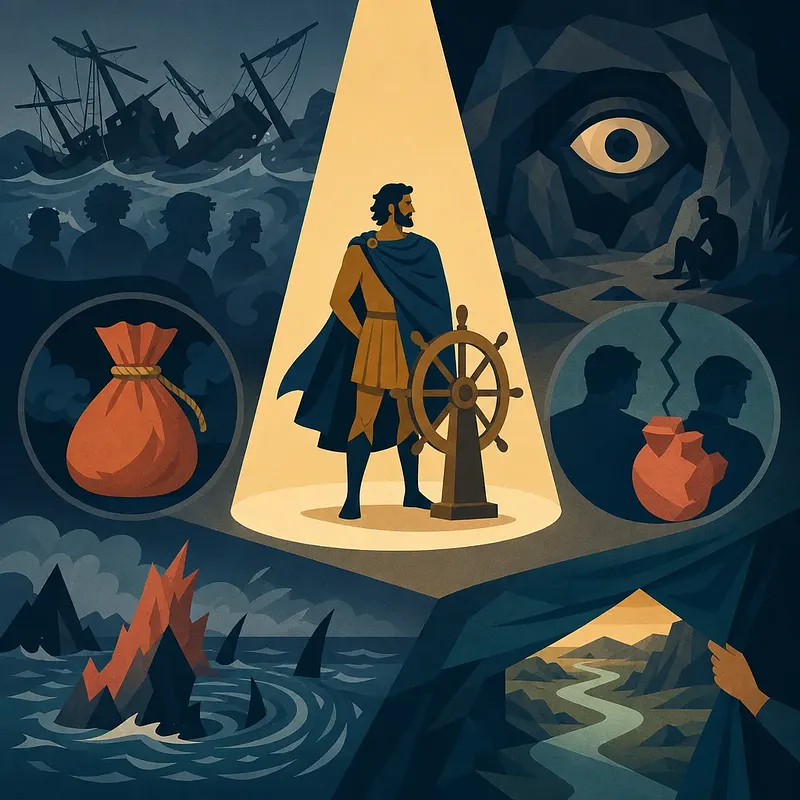
Odysseus is remembered as a hero because he achieved his goal of returning to Ithaca. From an organizational perspective, however, his voyage also ended in collective failure: none of his companions survived. This distinction matters for modern leadership. Results should not be assessed solely by whether the leader reaches the destination. We should also examine the information available at the time, viable alternatives, foreseeable harm, risk mitigation, and the treatment of team members. The story highlights how arrogance, withheld information, and collapsing trust can compound uncertainty. It also reveals narrative bias: the survivor was both the protagonist and the storyteller. #Leadership #DecisionMaking #OrganizationalCulture
Top 5 Agent Skills Compared: The Pitfalls of Popularity Rankings and Selection Criteria
Popularity metrics can help surface agent skill repositories, but they should not be treated as proof of quality. This article compares five repositories included in an August 10, 2026 snapshot and examines their features and design philosophies. A shared pattern among leading candidates is a structured workflow: clarify requirements, plan, test, make minimal changes, and verify results rather than coding immediately. The comparison also highlights practical selection risks. Loading a large bundle can increase context costs and create instruction conflicts, while external skills may introduce licensing, script execution, network, permission, token, or maintenance concerns. The key takeaway: evaluate only the skills you need and inspect how they operate before installation. #AgentSkills #AIAgents #GitHub