 Injoys
Social
A short written take on each piece of content: what changed and why it matters. Skim the point first, then follow through to the full article only for what interests you. Every take is drawn from real content, so the link takes you straight to the material it is based on.
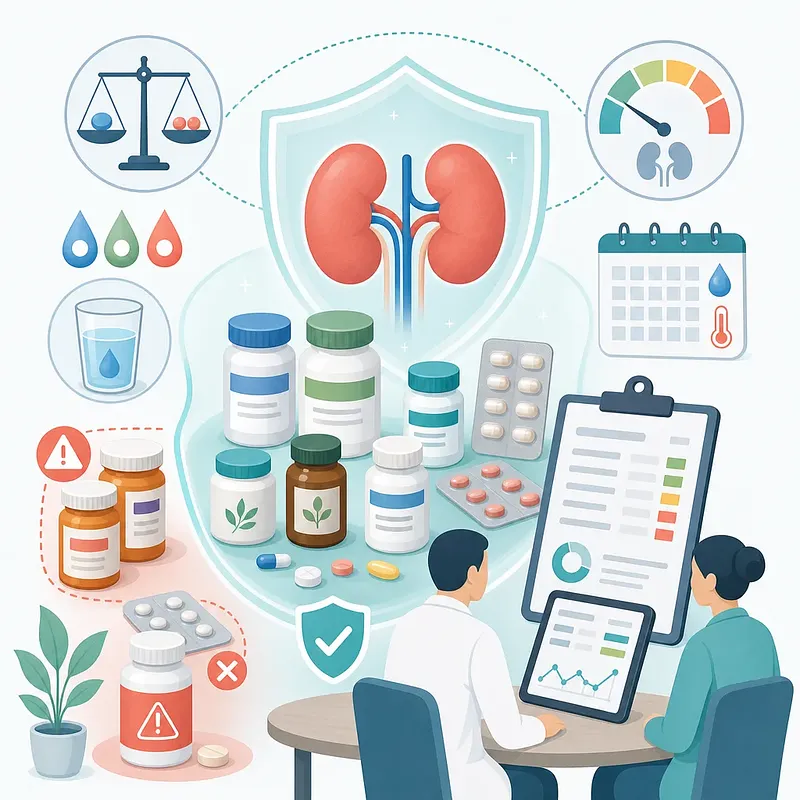
Medication management for kidney protection is about appropriateness—not simply reducing the number of drugs. Necessary prescriptions should generally be continued unless a healthcare professional recommends a change. Regular reviews can identify doses that do not match current kidney function, duplicate prescriptions, and unnecessary over-the-counter medicines or supplements. This article also outlines why dosing assessments may include glomerular filtration rate, electrolytes, hydration status, and drug-specific criteria. It highlights situations in which NSAIDs can increase acute kidney injury risk and explains the value of creating a personalized medication plan for illnesses involving dehydration or difficulty eating and drinking. #KidneyHealth #MedicationSafety #ChronicKidneyDisease
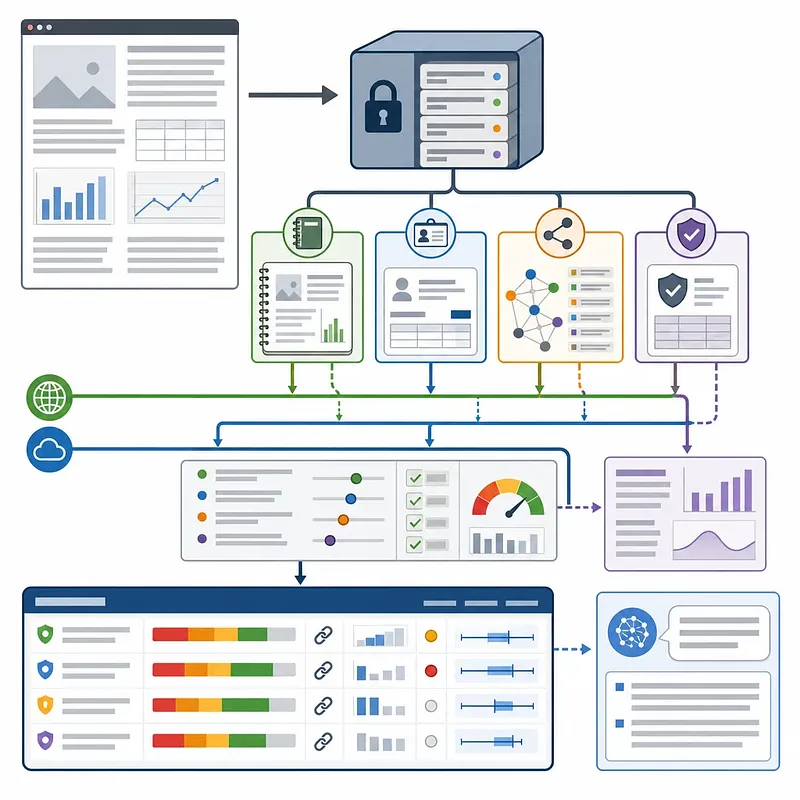
E-E-A-T is not an official Google score or a publicly disclosed formula for generative AI citations. That makes methodology especially important when GEO analysis tools attempt to quantify it. A reproducible approach fixes the webpage snapshot, evaluation rules, weights, and data-source versions. It also evaluates experience, expertise, authoritativeness, and trustworthiness through distinct evidence, keeping self-assertions separate from external verification. Rather than asking an LLM to determine the final score, the article proposes using code with fixed rules for calculation and reserving the LLM for evidence explanation. It also shows why E-E-A-T and AI citation likelihood should remain separate modules—and why every result should include evidence, missing-data status, decision rules, and confidence. #AI #AIDevelopment #TechnologyStrategy
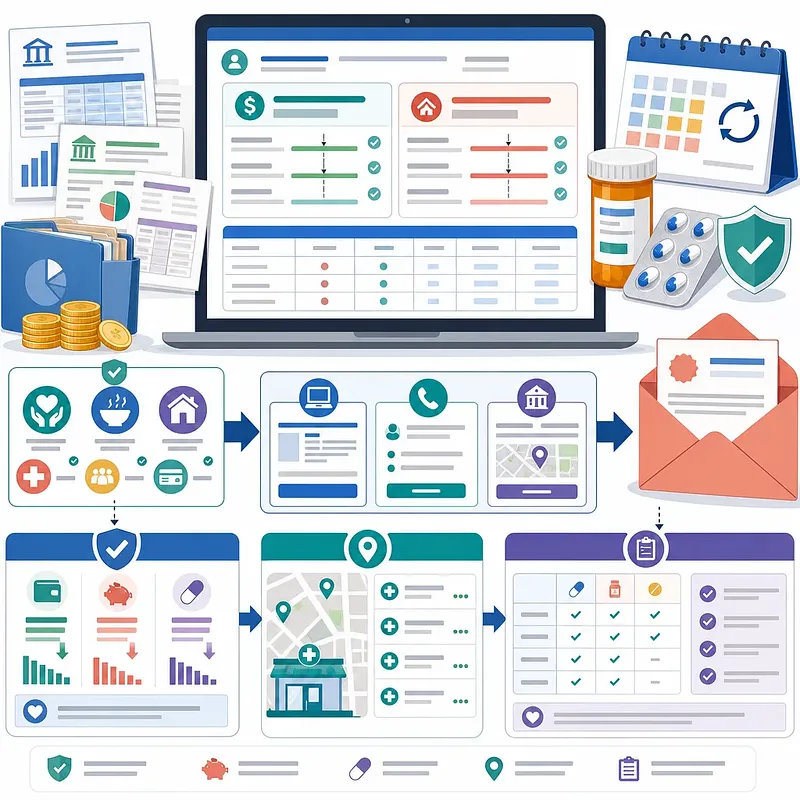
Understanding Medicare Extra Help eligibility can make a meaningful difference in prescription drug expenses. For 2026, the general limits are $23,940 in annual income and $18,090 in assets for individuals, and $32,460 in income and $36,100 in assets for couples. The article explains automatic qualification through Medicaid, certain Medicare Savings Programs, or SSI; documents applicants may need; and how to apply through Social Security at any time. It also covers why people slightly above the limits may still want to apply and what to review in a Part D plan after approval. #Medicare #HealthInsurance
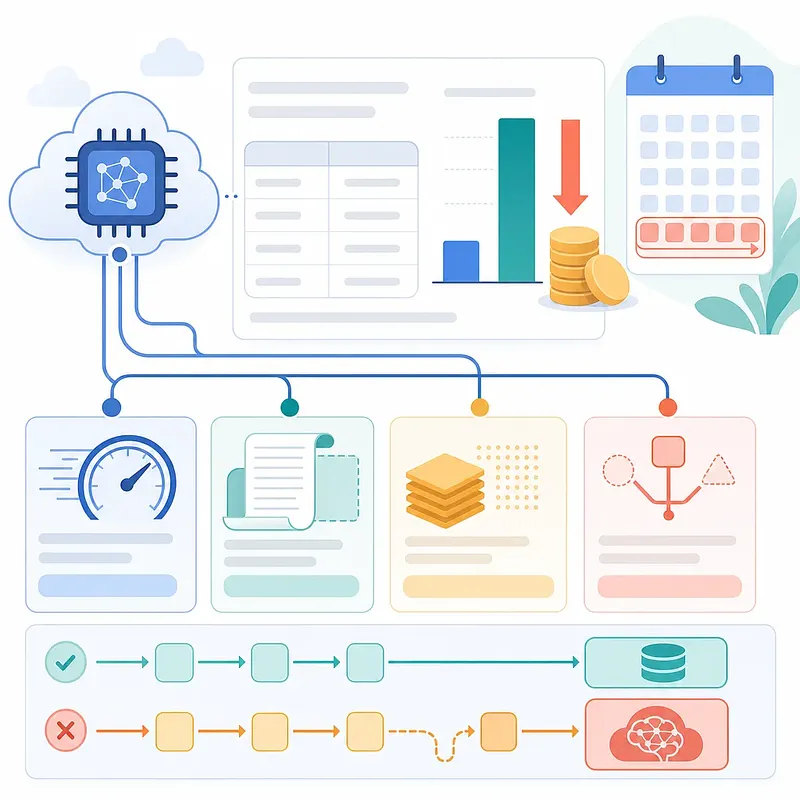
OpenAI’s promotional pricing for GPT-5.6 Sol could materially change API cost forecasts. The standard rate is now $400 per 1 million input tokens and $2,000 per 1 million output tokens, with availability through at least November 21, 2026. The reductions also cover fast mode, long-context requests, Batch, and Flex processing, although teams should verify the applicable rate for their processing method and account terms. Why it matters: output tokens cost five times more than input tokens. Response length and repeated agent iterations can therefore have a substantial effect on actual spending. The article breaks down the announced reductions, promotion timing, and practical cost considerations. #AIDevelopment #OpenAI
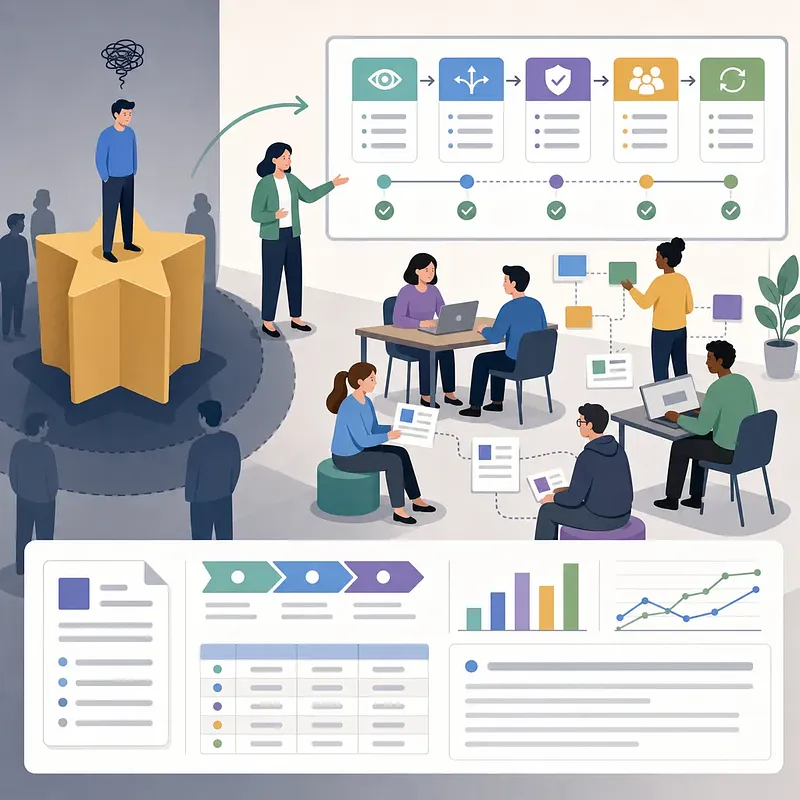
Why Calling a Star Performer a “Genius” Can Ruin Them
A star performer delivers again. Calling them a “genius” may reward the result while making failure and help-seeking feel costlier. Fixed-ability praise can create an identity the recipient feels pressure to protect. Useful recognition works more like learning data. The article explains how to connect the observed situation and behavior to their impact, then identify what can be repeated. It also distinguishes effective strategy, revision, collaboration, and verification from unconditional praise for talent or effort. Result-only praise carries team-level risks: work concentration, knowledge hoarding, overwork, and dependence on one person. Timely feedback matters, but public or private delivery should reflect the recipient’s preferences and organizational context. Leaders, managers, and people professionals supporting high performers can use this framework to make recognition clearer and more transferable. Read the article before the next feedback conversation. #Leadership #PsychologicalSafety
Google's AI Strategy: Why Distribution and Inference Economics Matter More Than Model Competition
Model quality matters, but it is only one component of AI market competition. Google’s strategic position depends heavily on distribution and inference economics: Gemini can be deployed across Search, Android, Chrome, Workspace, and Cloud, while proprietary TPUs may lower the cost of serving responses at scale. The article also explains why advertising assumptions require caution. The presence of ads in AI Overviews does not prove that longer AI answers automatically generate more revenue. A stronger assessment focuses on user retention, task success rates, cost per response, and changes in existing search revenue. These operating metrics may reveal more than benchmark rankings alone. #AI #GenerativeAI